Human phylogenetics at scale
A phylogeny is a hypothesis about who descends from whom. Build one from a few hundred sequences and you can check it by eye. Build one from a third of a million and almost nothing in the standard phylogenetics toolkit survives contact with the data.
The tree everyone was using had stopped keeping up
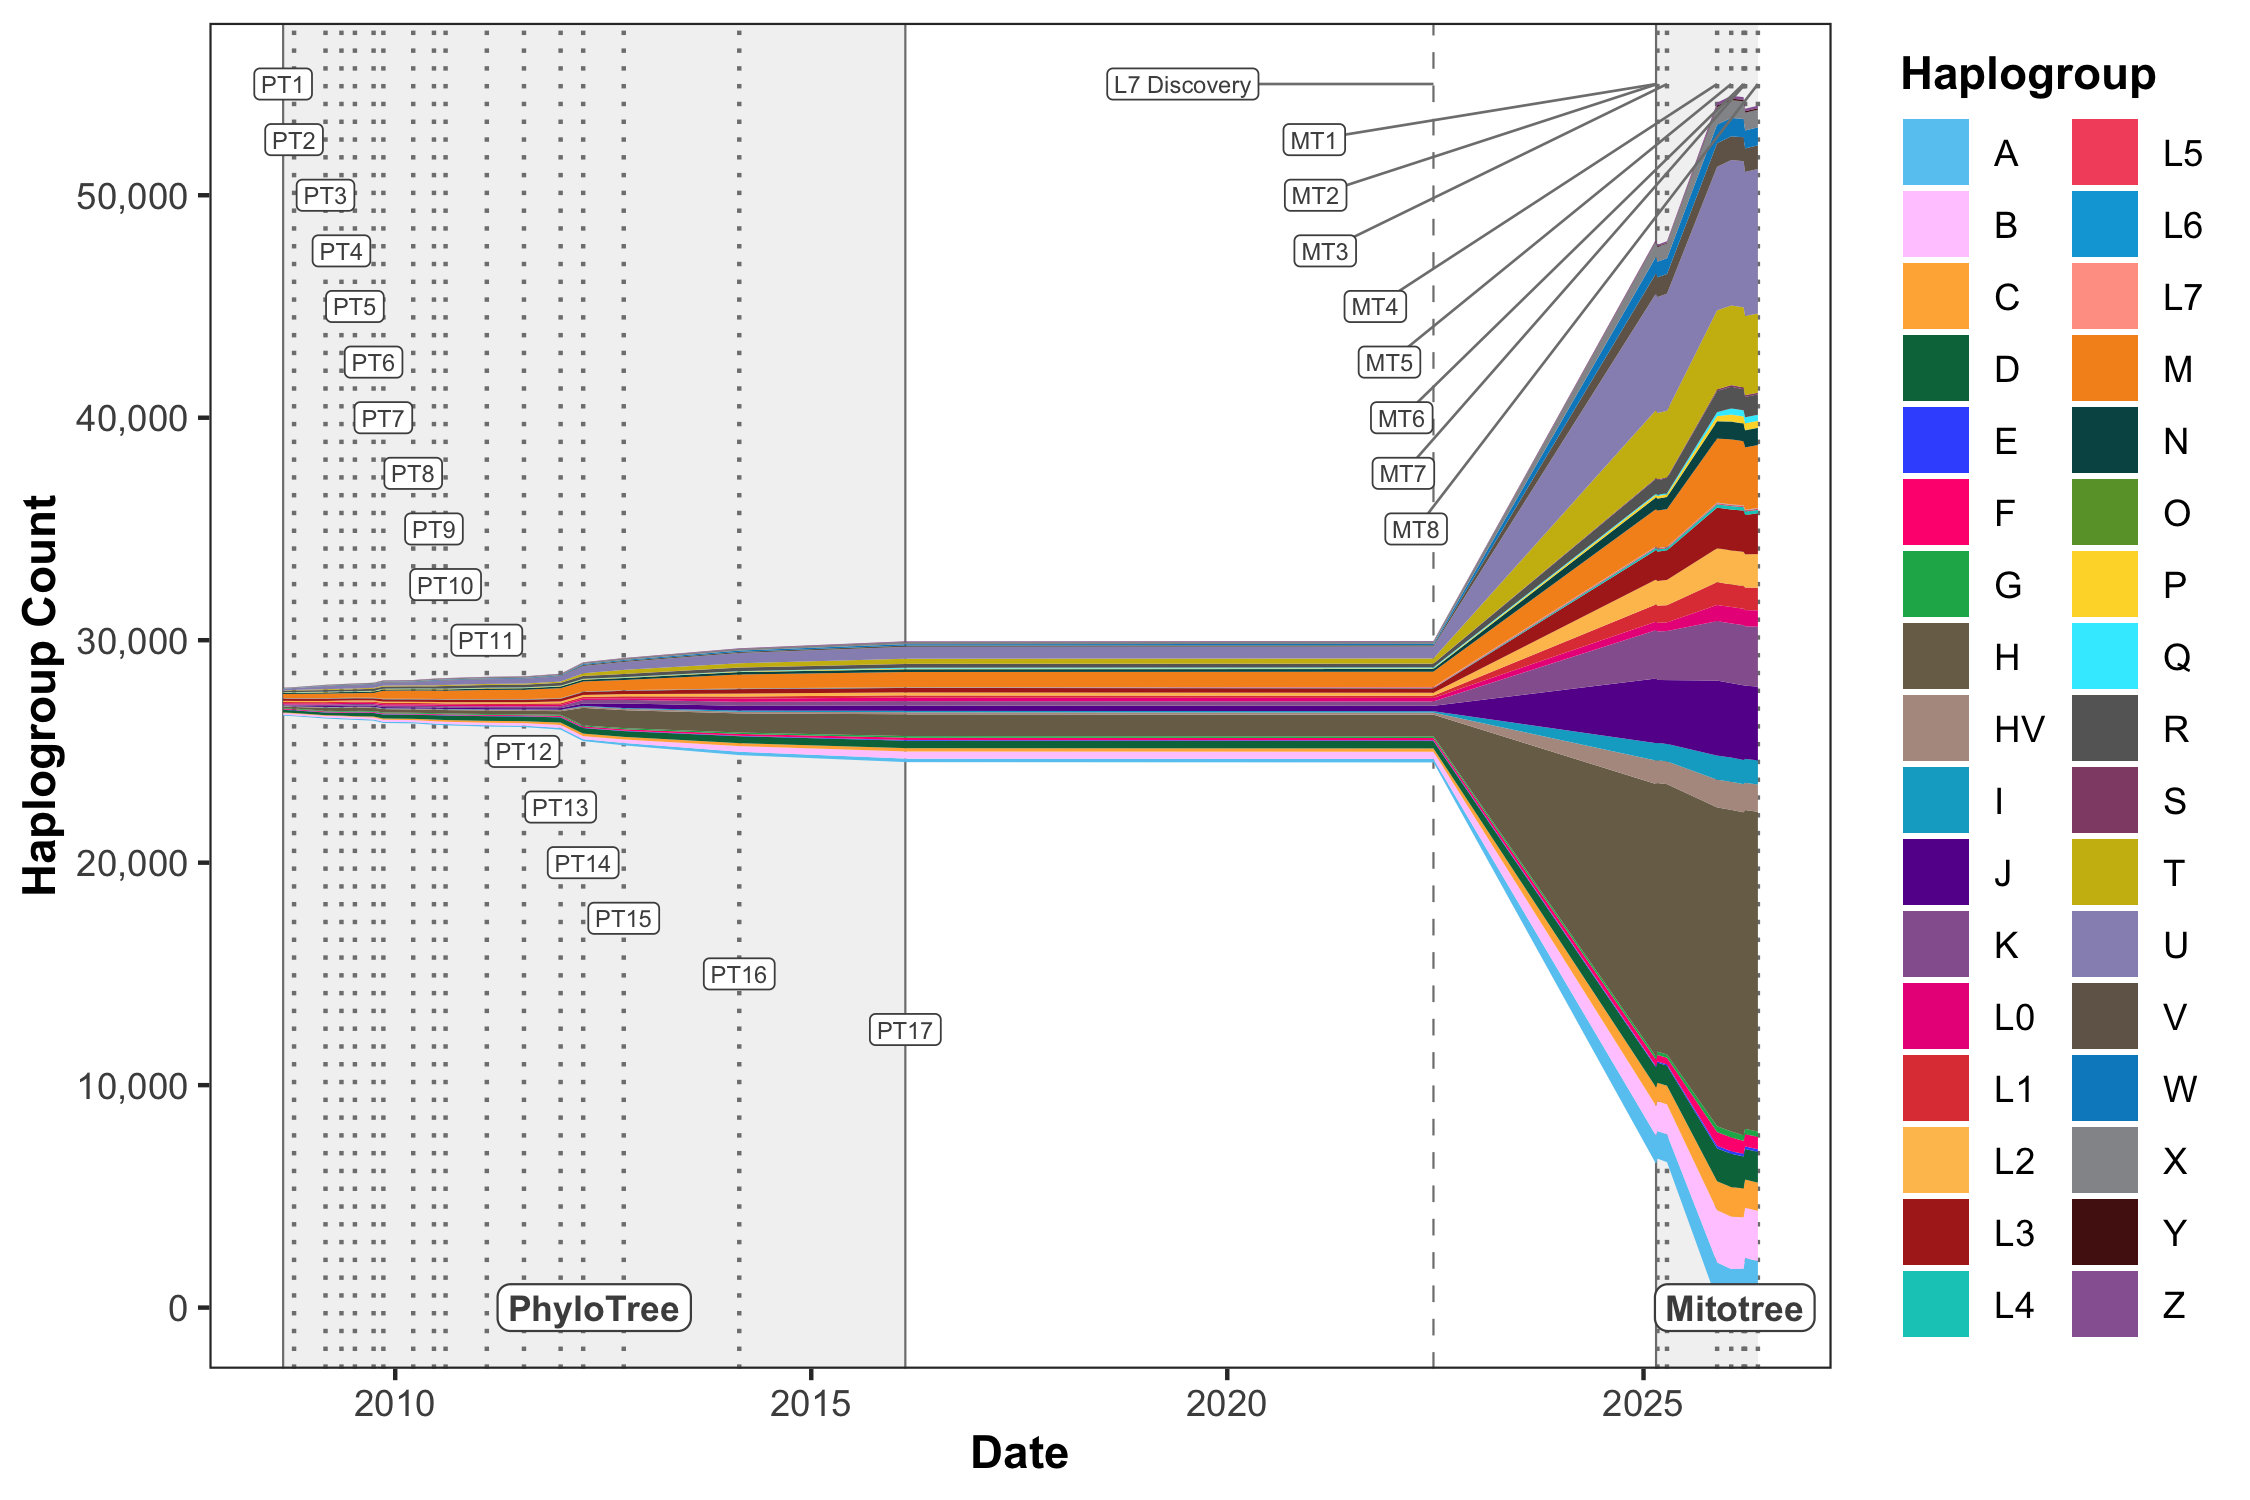
PhyloTree v17 was published in 2016. It described about 5,400 haplogroups and quietly became the thing that nearly every lab, consumer test, and forensic pipeline depended on. It was a genuinely good resource. The problem was that it stopped being rebuilt.
Meanwhile sequencing costs collapsed and the number of available mitogenomes grew by more than an order of magnitude. When a reference tree stops being re-estimated, new sequences get grafted onto an increasingly outdated scaffold. Errors do not announce themselves; they accumulate quietly, and every downstream result inherits them.
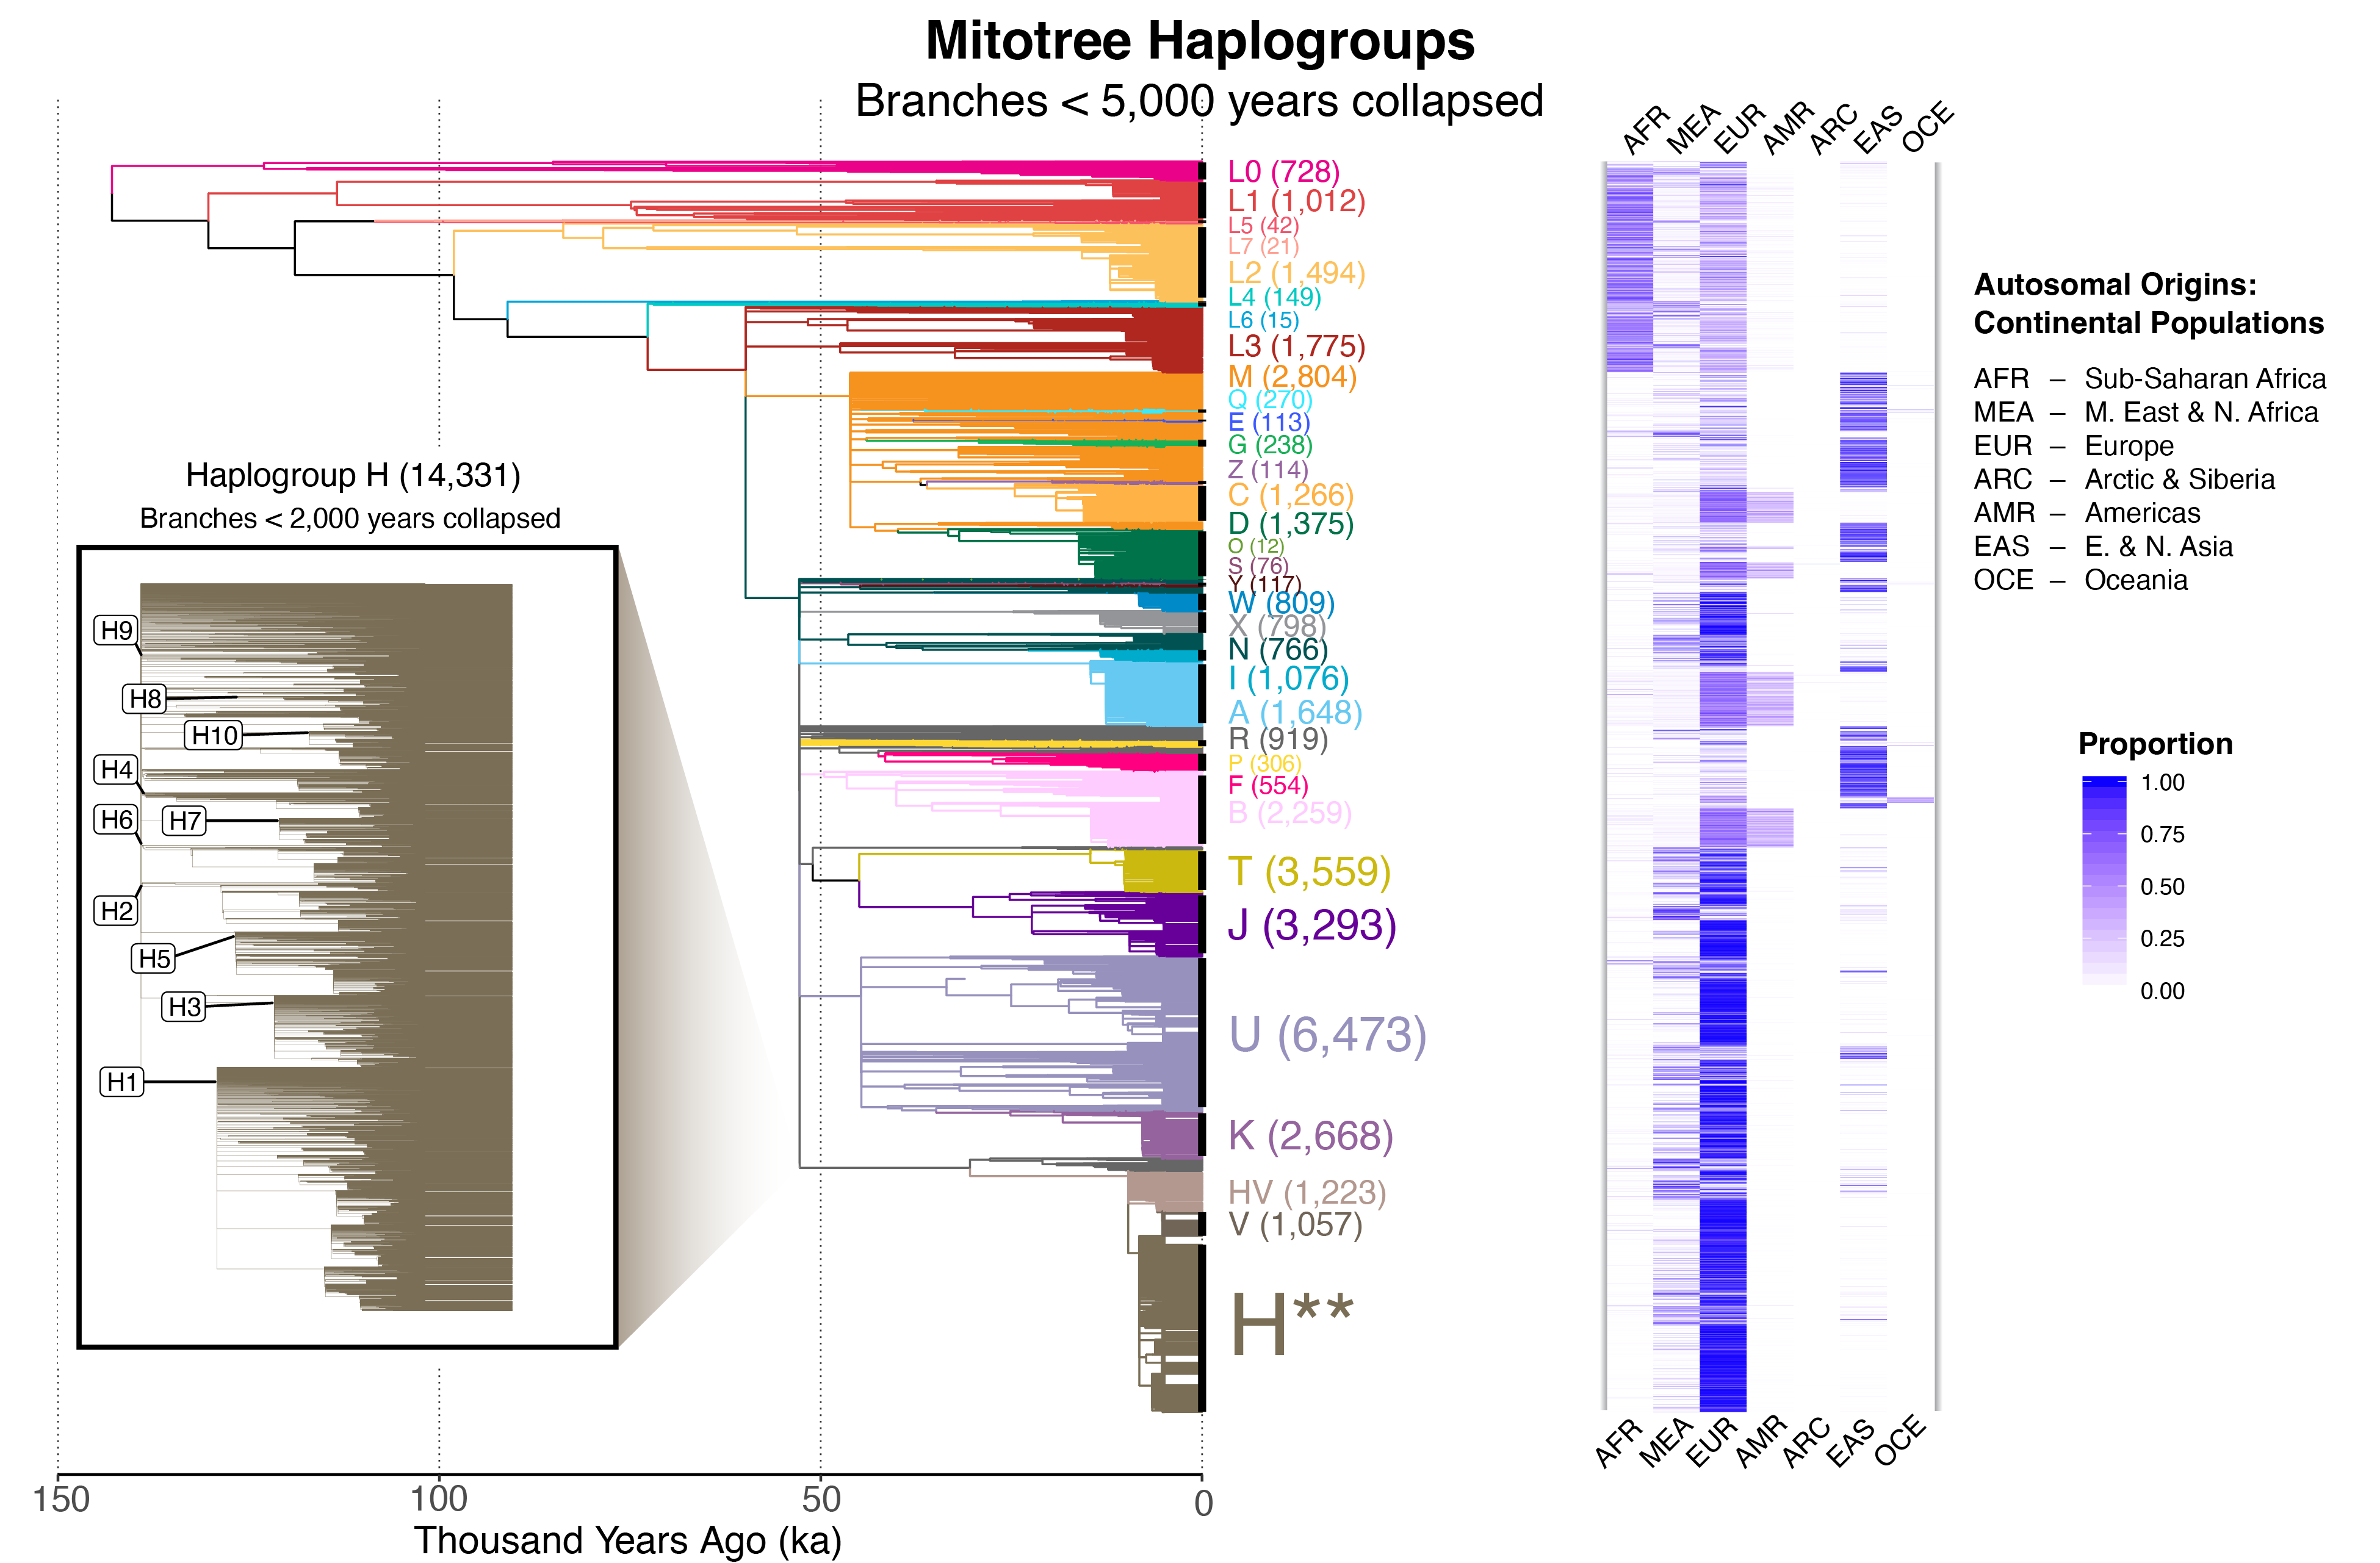
Mitotree is the replacement. It resolves 53,588 haplogroups from 331,221 complete mitochondrial genomes, which collapse to 177,196 unique haplotypes once identical sequences are merged. That is roughly ten times the resolution of the previous standard, and it was built from scratch rather than grafted onto what came before.
Why it had not been done
Two problems stood in the way, and they are different in kind.
The first is search. Finding a good tree means evaluating an astronomically large space of possible topologies, and the heuristics that do this well had never been benchmarked above roughly 50,000 sequences. Above that they either failed outright or returned error rates nobody would accept. Several groups had tried.
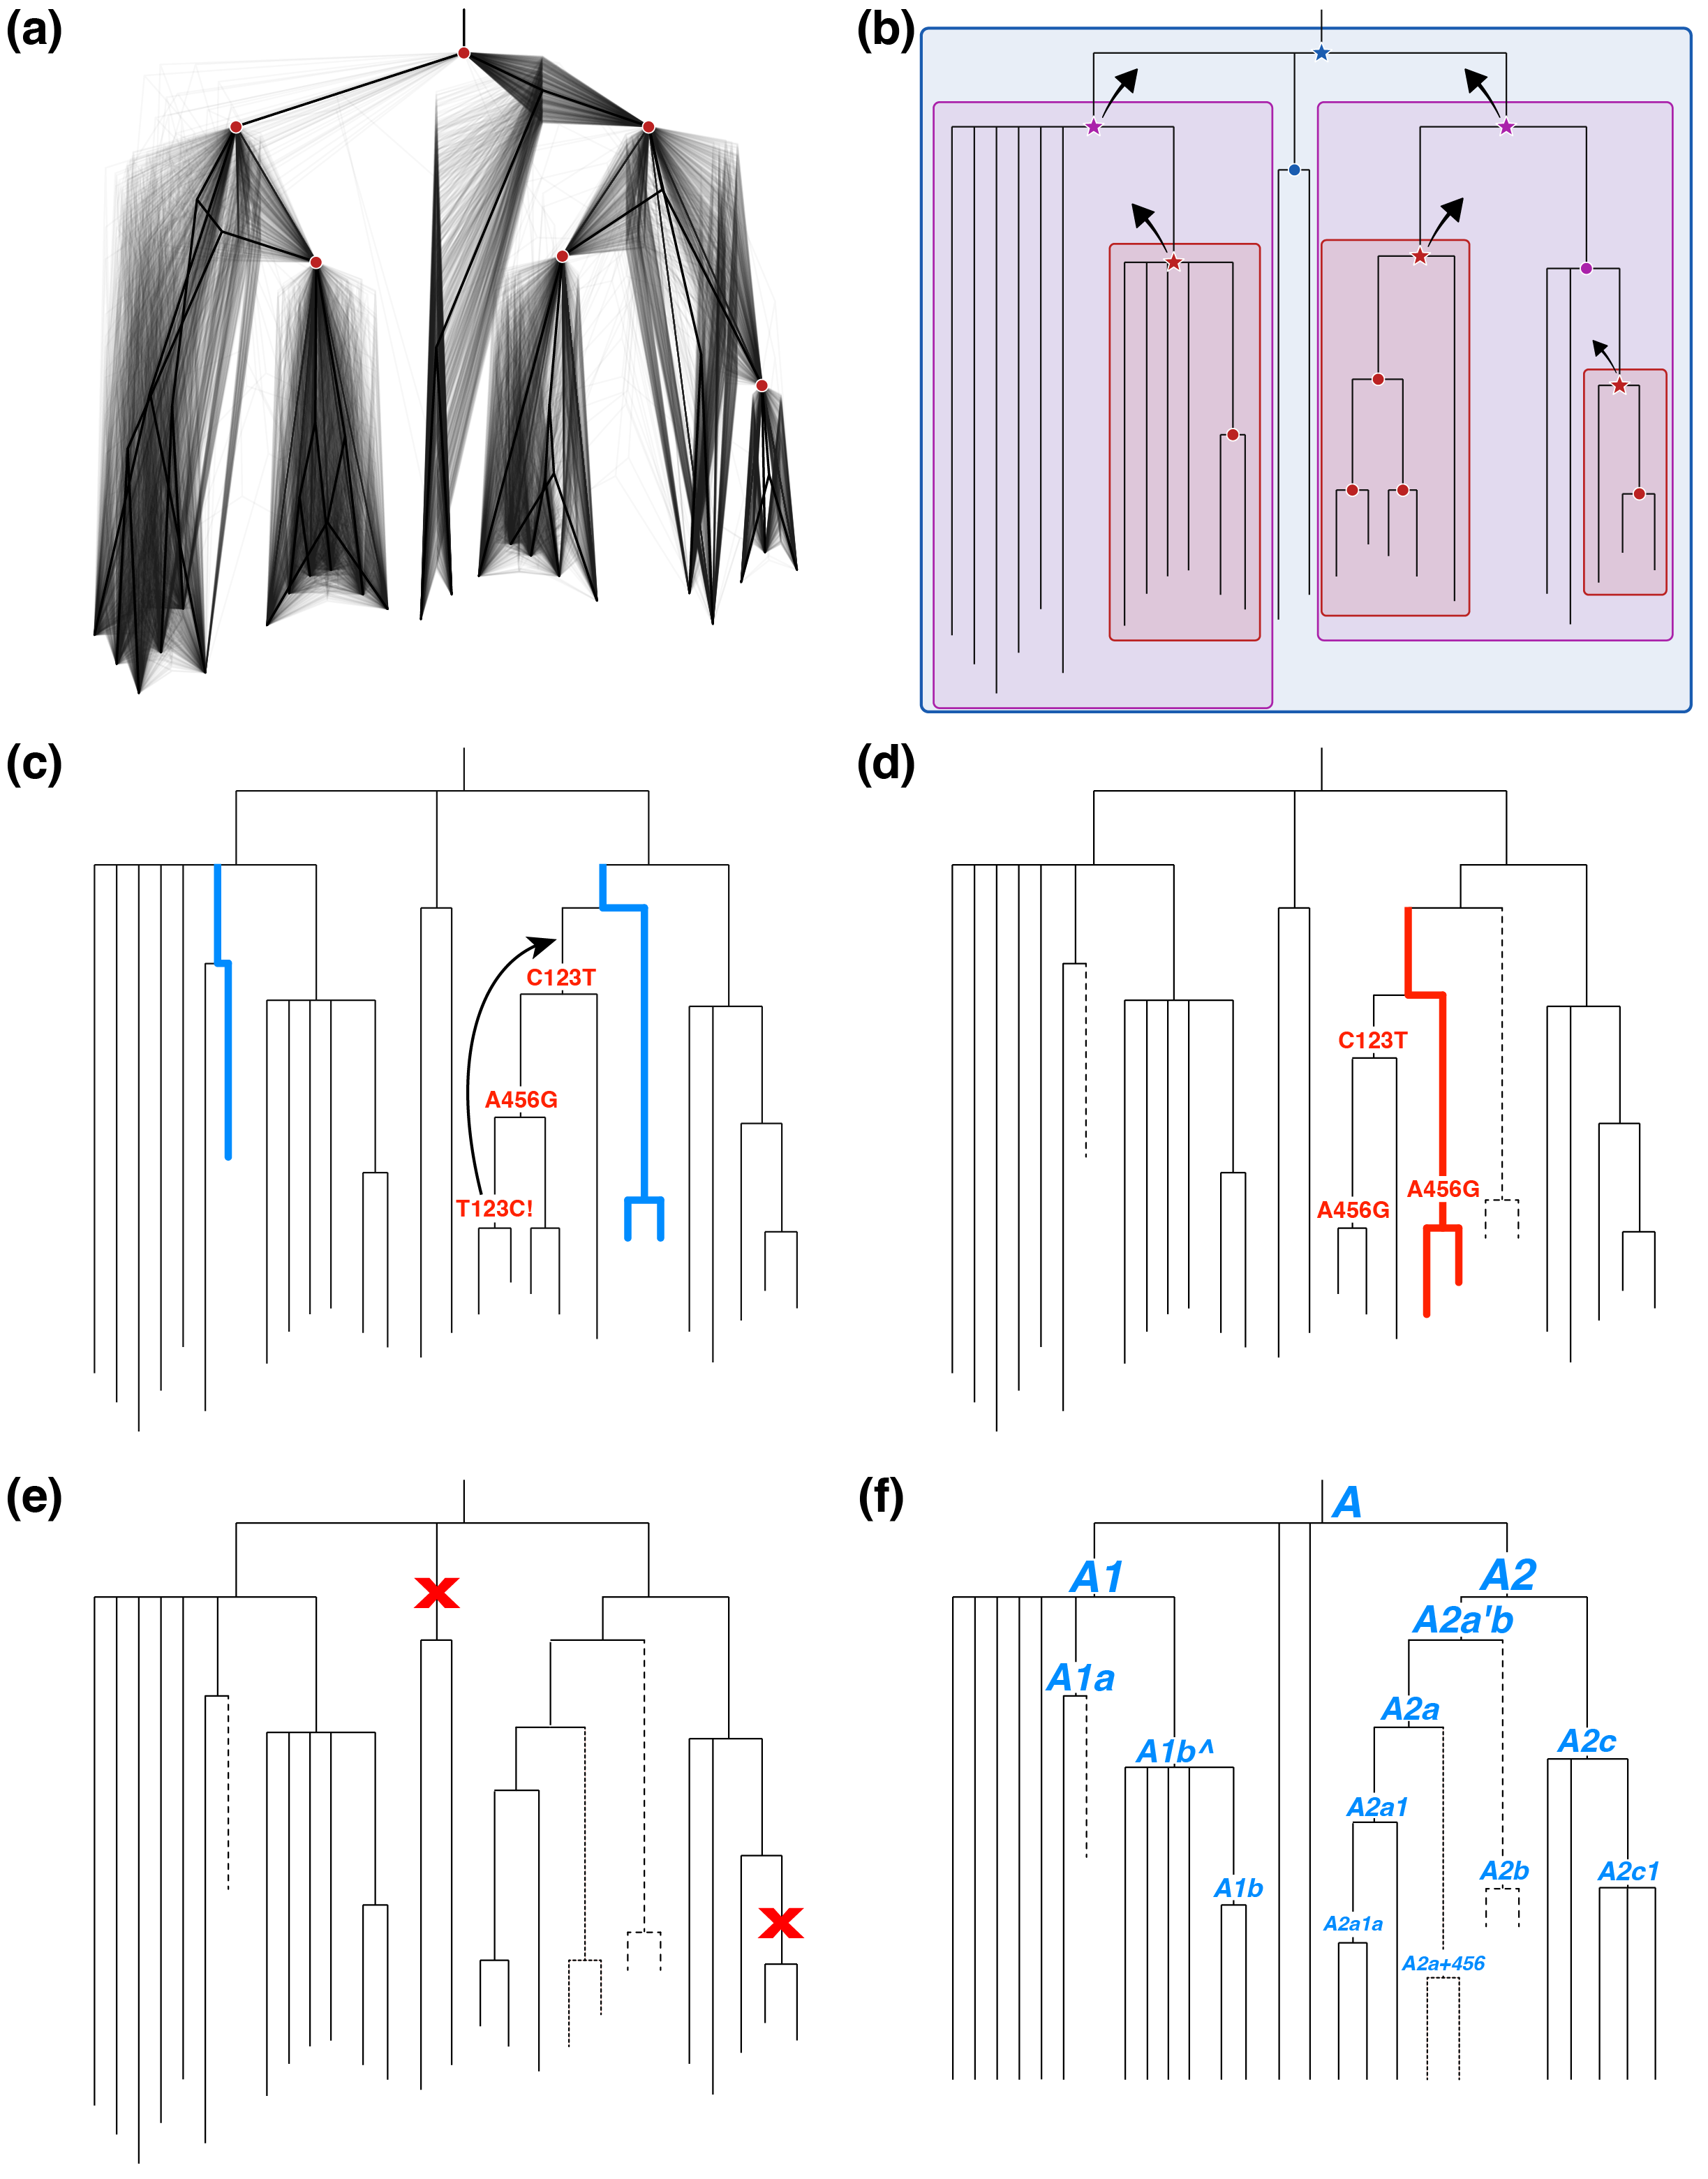
The solution was a recursive divide-and-conquer framework. It breaks the problem into tractable subproblems, runs weighted parsimony searches on each, and reassembles them, with the reassembly step designed so that decisions made locally do not lock in mistakes globally. It handles 175,000 haplotypes, which is 3.5× the largest dataset previously benchmarked in the literature.
The second problem is knowing whether the answer is right. A tree this size cannot be checked by inspection, and there is no independent ground truth for human matrilineal descent. So I generated simulated phylogenies where the true answer was known by construction and ran the entire pipeline over them, end to end, exactly as it runs on real data.
Across ten replicate simulations the pipeline recovered branches with a 3.5% false negative rate and a 1.0% false positive rate. Benchmarked against FastTree2, the only alternative that scales comparably, it performs substantially better on topological accuracy.
I also built a three-part node support metric, because “how confident are we in this branch” turns out to be three separate questions. A branch can be uncertain because there were not enough informative sites, because the search did not converge, or because the mutations genuinely conflict with each other. Collapsing those into one number hides the thing you most want to know, which is whether more data or more compute would help.
The pipeline runs in six stages. Find the nodes that every rough search agrees on. Use those as scaffolding to break an intractable problem into tractable ones. Solve each piece properly. Downweight evidence you do not trust. Correct the mutations that lie. Throw out the branches you cannot defend. Then put time on the result.
Everything upstream of the tree
Most of the work in a project like this is not phylogenetics. Before a single tree search runs, a third of a million samples have to be aligned, called, and filtered, and the filters matter enormously. Heteroplasmy, ambiguous base calls, reference bias, and post-mortem damage in ancient samples each produce characteristic artifacts that look exactly like real mutations and will happily anchor a spurious branch that then propagates through everything downstream.
Technical details
Variant calling follows an automated pipeline adapted from GATK Best Practices for mitochondrial short variant discovery, using GATK 4.6, BWA-MEM, and BCFtools. QC applies explicit screens for heteroplasmy, depth, ambiguity, contamination, and reference bias, and can exclude an entire contributing study when it shows systematic artifacts. Alignment is normalized around the known problem regions of the mitochondrial genome with MUSCLE, and markers are weighted by how consistently they behave across the dataset rather than treated as equally trustworthy.
Tree search runs weighted parsimony in TNT under the recursive divide-and-conquer framework, with IQ-TREE2 used for comparison. Downstream manipulation and support calculation use the R packages ape, phytools, phangorn, and treeio.
Divergence times come from a relaxed molecular clock in LSD, calibrated against BEAST, with 3,206 radiocarbon-dated ancient samples supplying age constraints on the branches where they fall. The finished tree is distributed through HaploGrep v3 plugins, so an external lab can assign haplogroups against Mitotree without changing anything about its existing workflow.
Haplogroup L7: an eighth African lineage hiding in public data
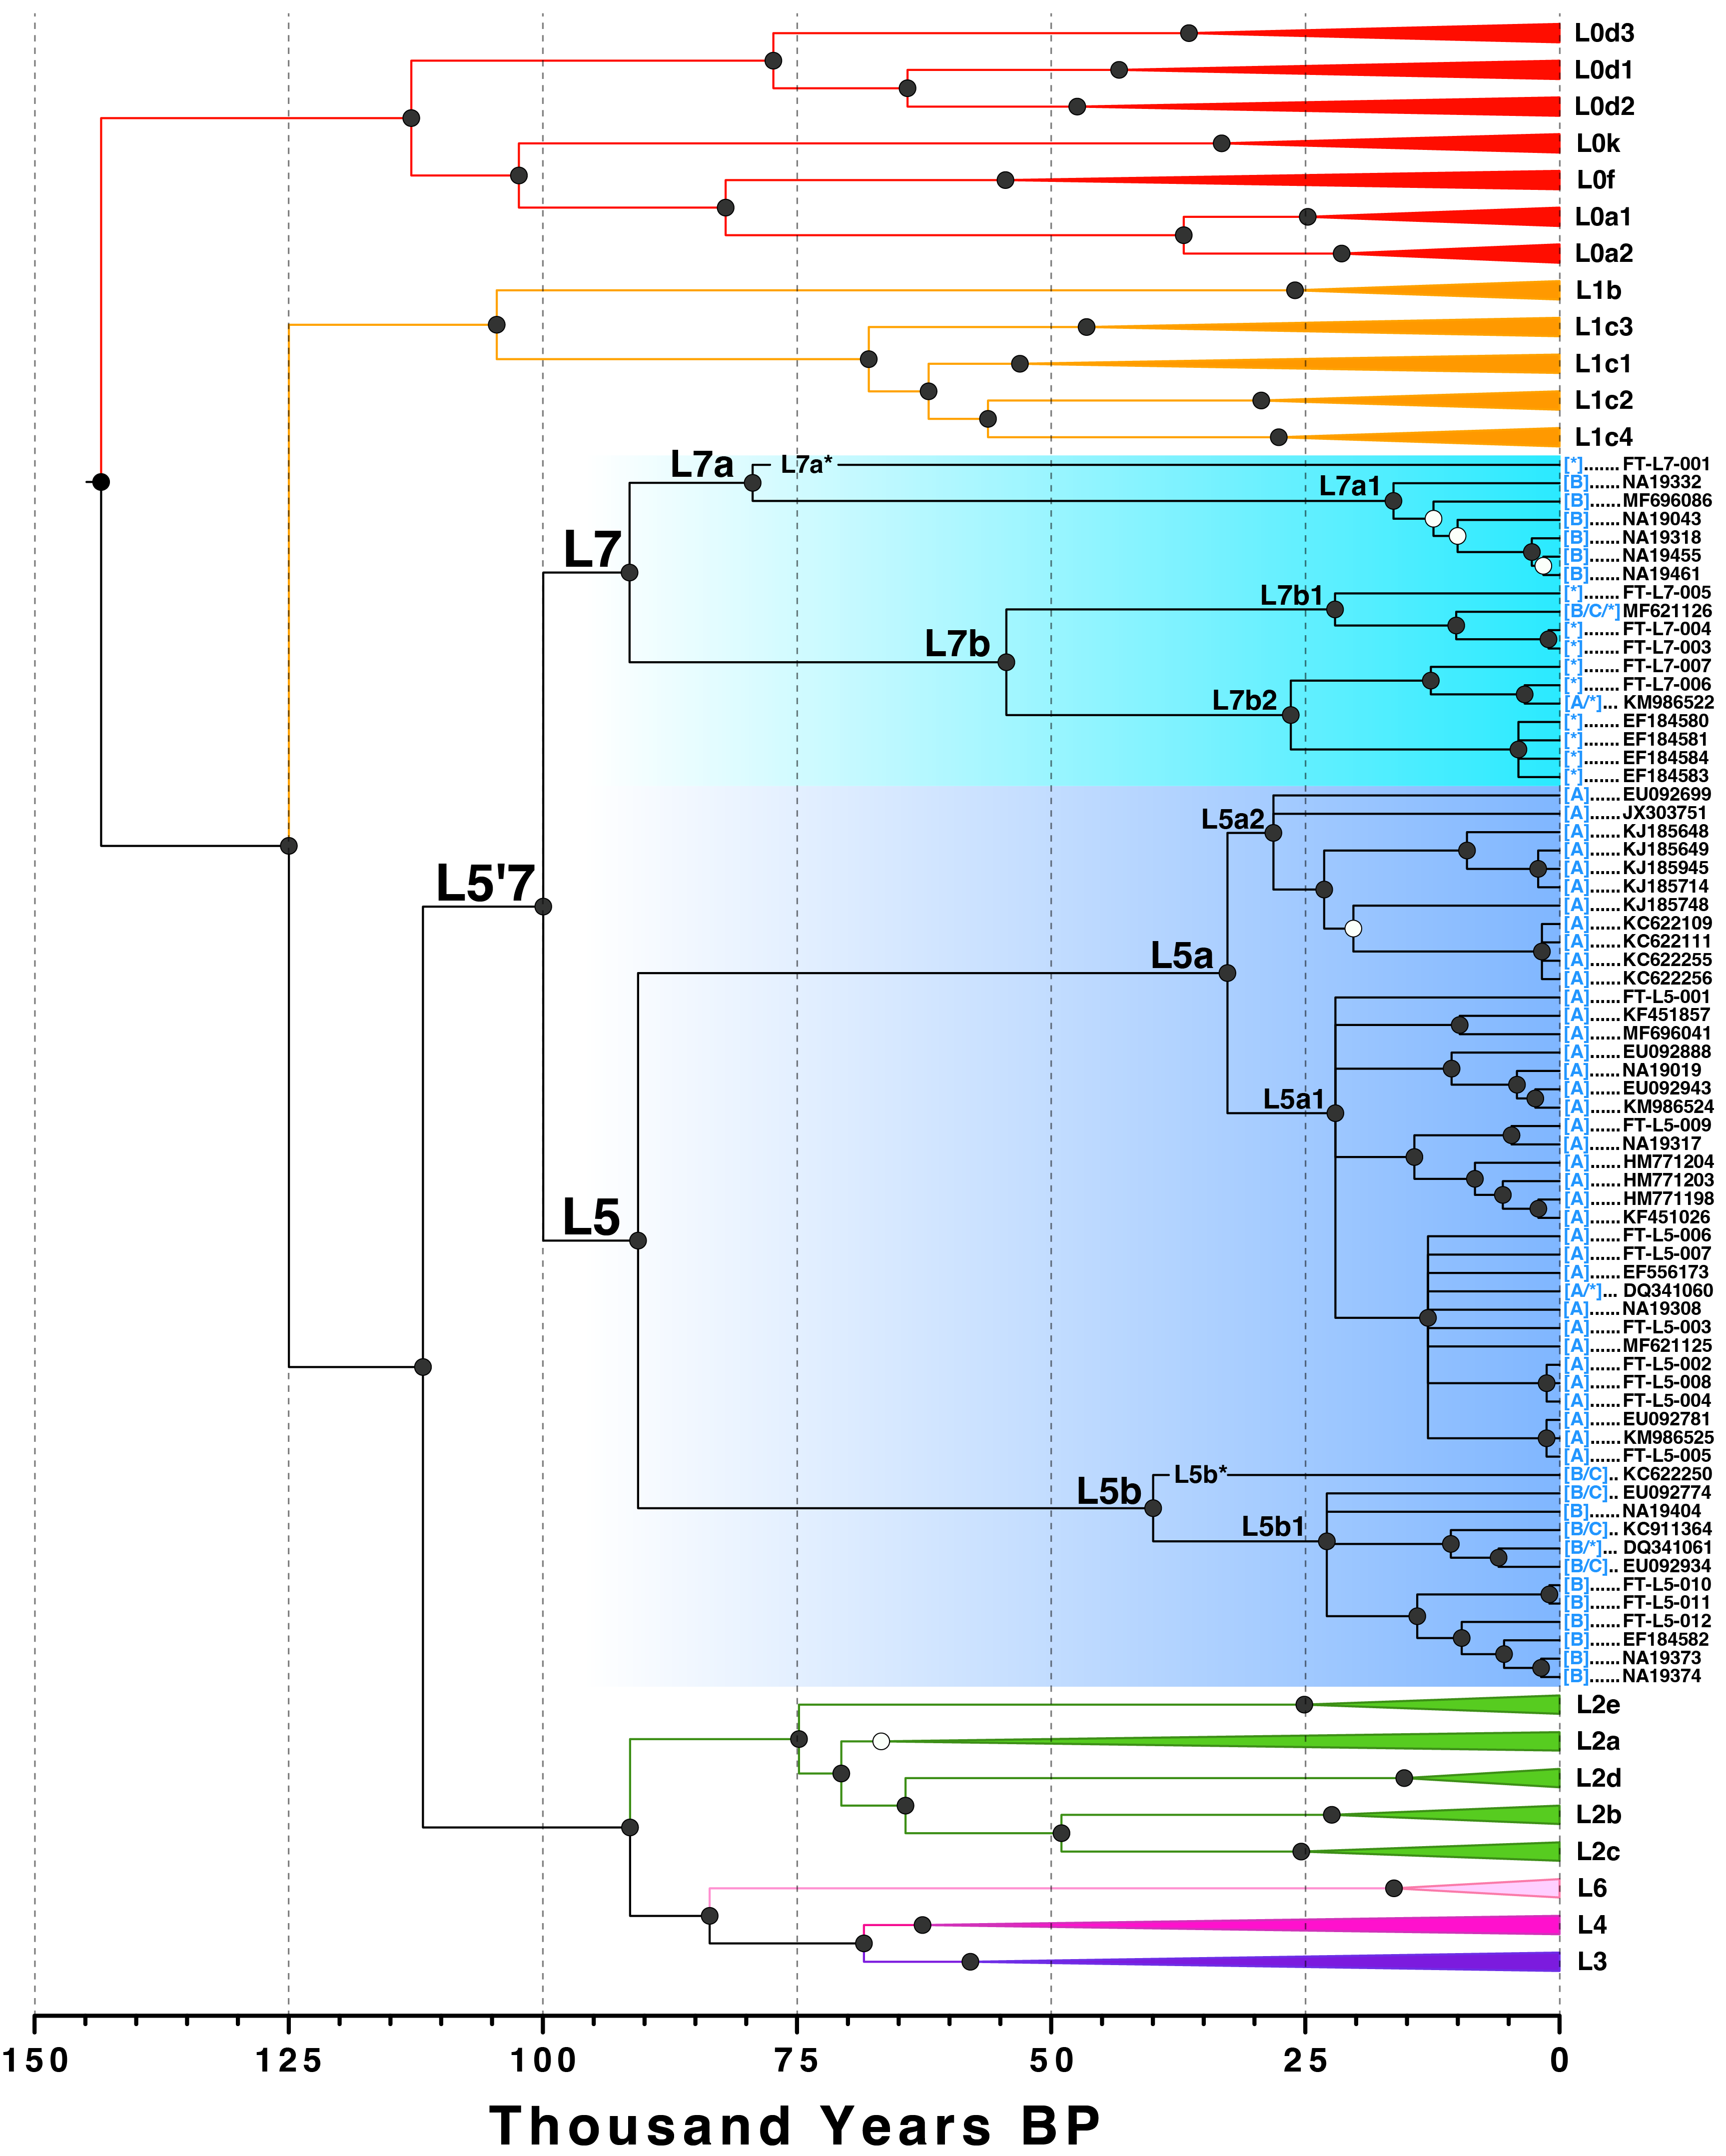
Modern humans have been around for something like 300,000 to 500,000 years, but global mitochondrial diversity coalesces to a single African ancestor roughly 145,000 years ago, because the matrilineal haploid genome has a quarter the effective population size of the autosomes. Most of human prehistory therefore played out in Africa, and the deepest structure in the mitochondrial tree is African structure.
For nearly two decades that structure was described by seven basal haplogroups, L0 through L6. They formed the backbone of the tree. Working through sequences that were already published, alongside newly generated ones, we found an eighth.
L7 is roughly 100,000 years old and had been misclassified in the literature. Its sublineage L7a* is the oldest singleton branch known in the human mitochondrial tree at about 80,000 years, meaning a lineage that split that long ago and is represented today by a single sampled sequence.
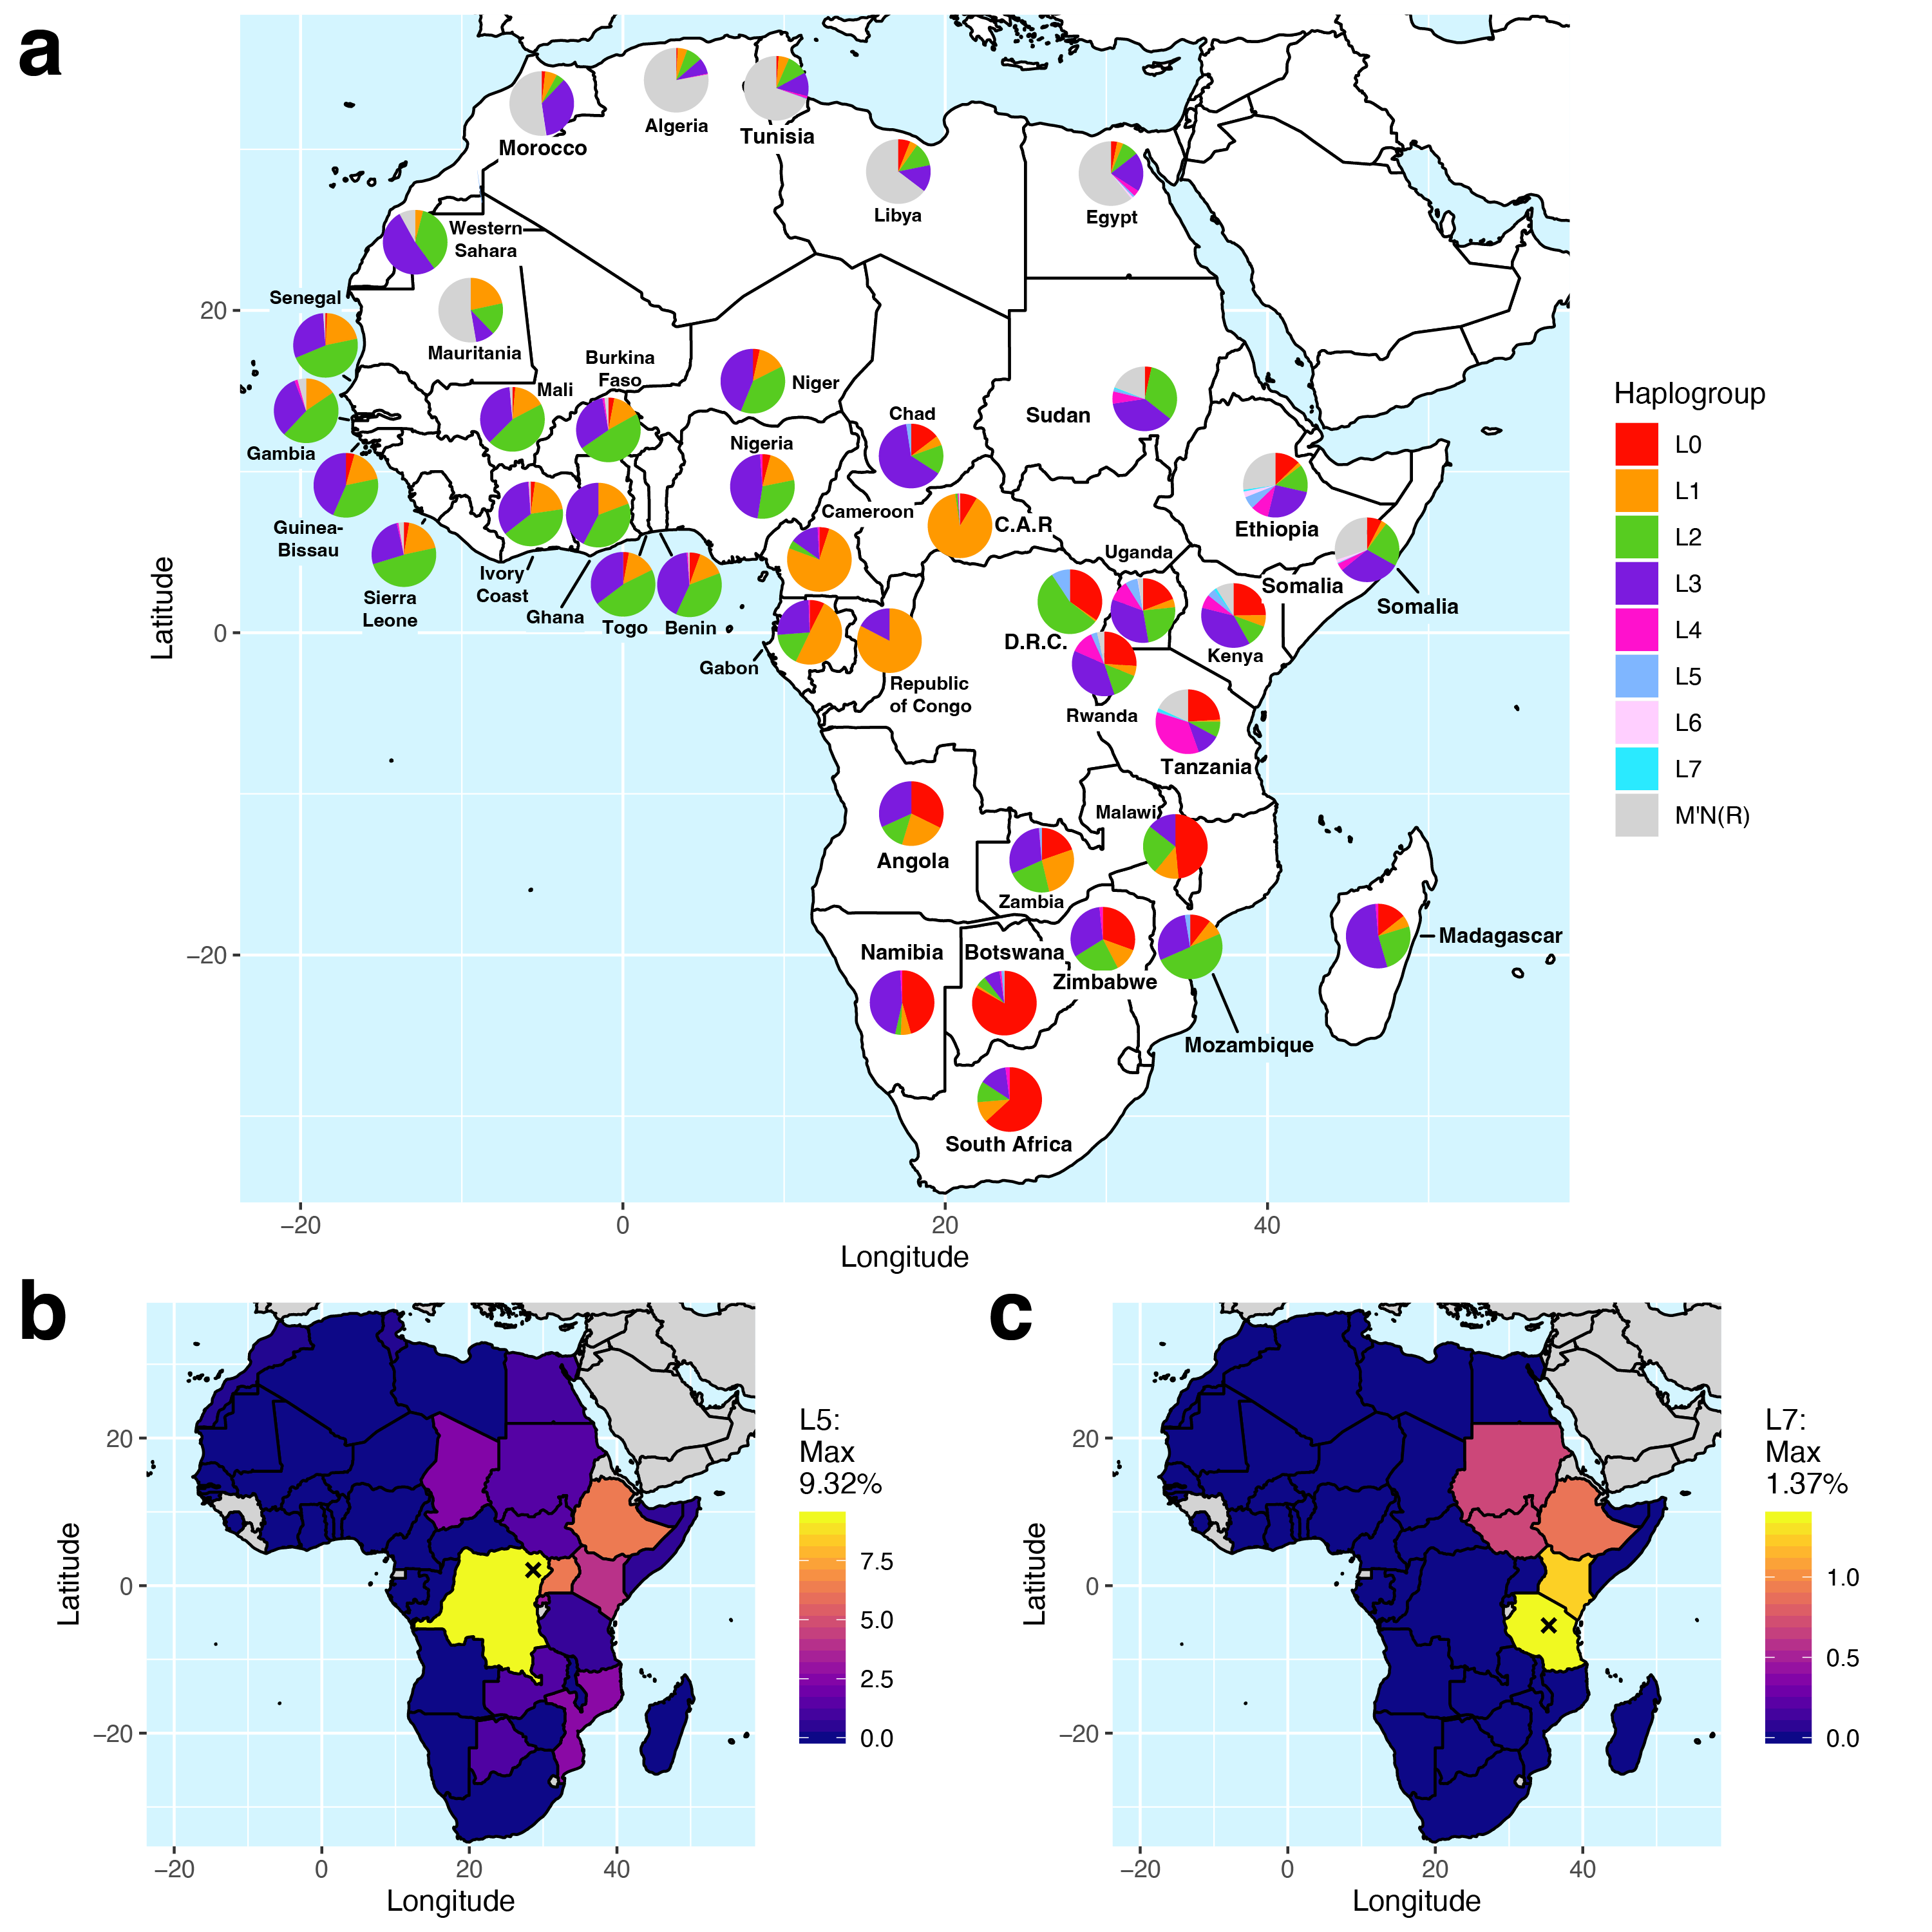
L7 and its sister group L5 are both low-frequency relics centered on East Africa, but they sit in different populations. L7 turns up among the Sandawe, L5 among the Mbuti. Three small subclades of African foragers hint at where the combined L5’7 lineage originated, but most subclades divide into Afro-Asiatic and eastern Bantu groups, which reflects more recent admixture rather than ancient structure.
The general lesson is the one that led directly to Mitotree. A reference phylogeny is not a finished object. It needs regular re-estimation, or new samples get placed onto a scaffold that is drifting further from the data every year.
Technical details
Phylogenetic inference and divergence dating used BEAST 2.5 on SNP markers only, with the mitochondrial genome partitioned six ways so that relative rates across coding regions, tRNAs, and non-coding regions could be estimated and fixed to the mean overall rate. INDELs were identified and annotated to PhyloTree v17 conventions for annotation purposes but excluded from inference, since positions such as 309 and 315 carry high recurrence and alignment ambiguity.
The tree prior was a non-parametric Bayesian skyline, chosen so as not to assume anything in advance about population size or tree shape through time. Two independent chains of 5×10⁷ MCMC steps sampled every 103, with Tracer used to confirm stationarity within and between runs.
Clade-defining ancestral variants were estimated by maximum likelihood ancestral state reconstruction using the ace function in ape, after converting the tree into a hierarchical structure with data.tree.
Dating the paternal tree
A tree tells you the order of events. It does not tell you when they happened. Converting branch length into years is divergence dating, and it has been a live problem since the 1960s.
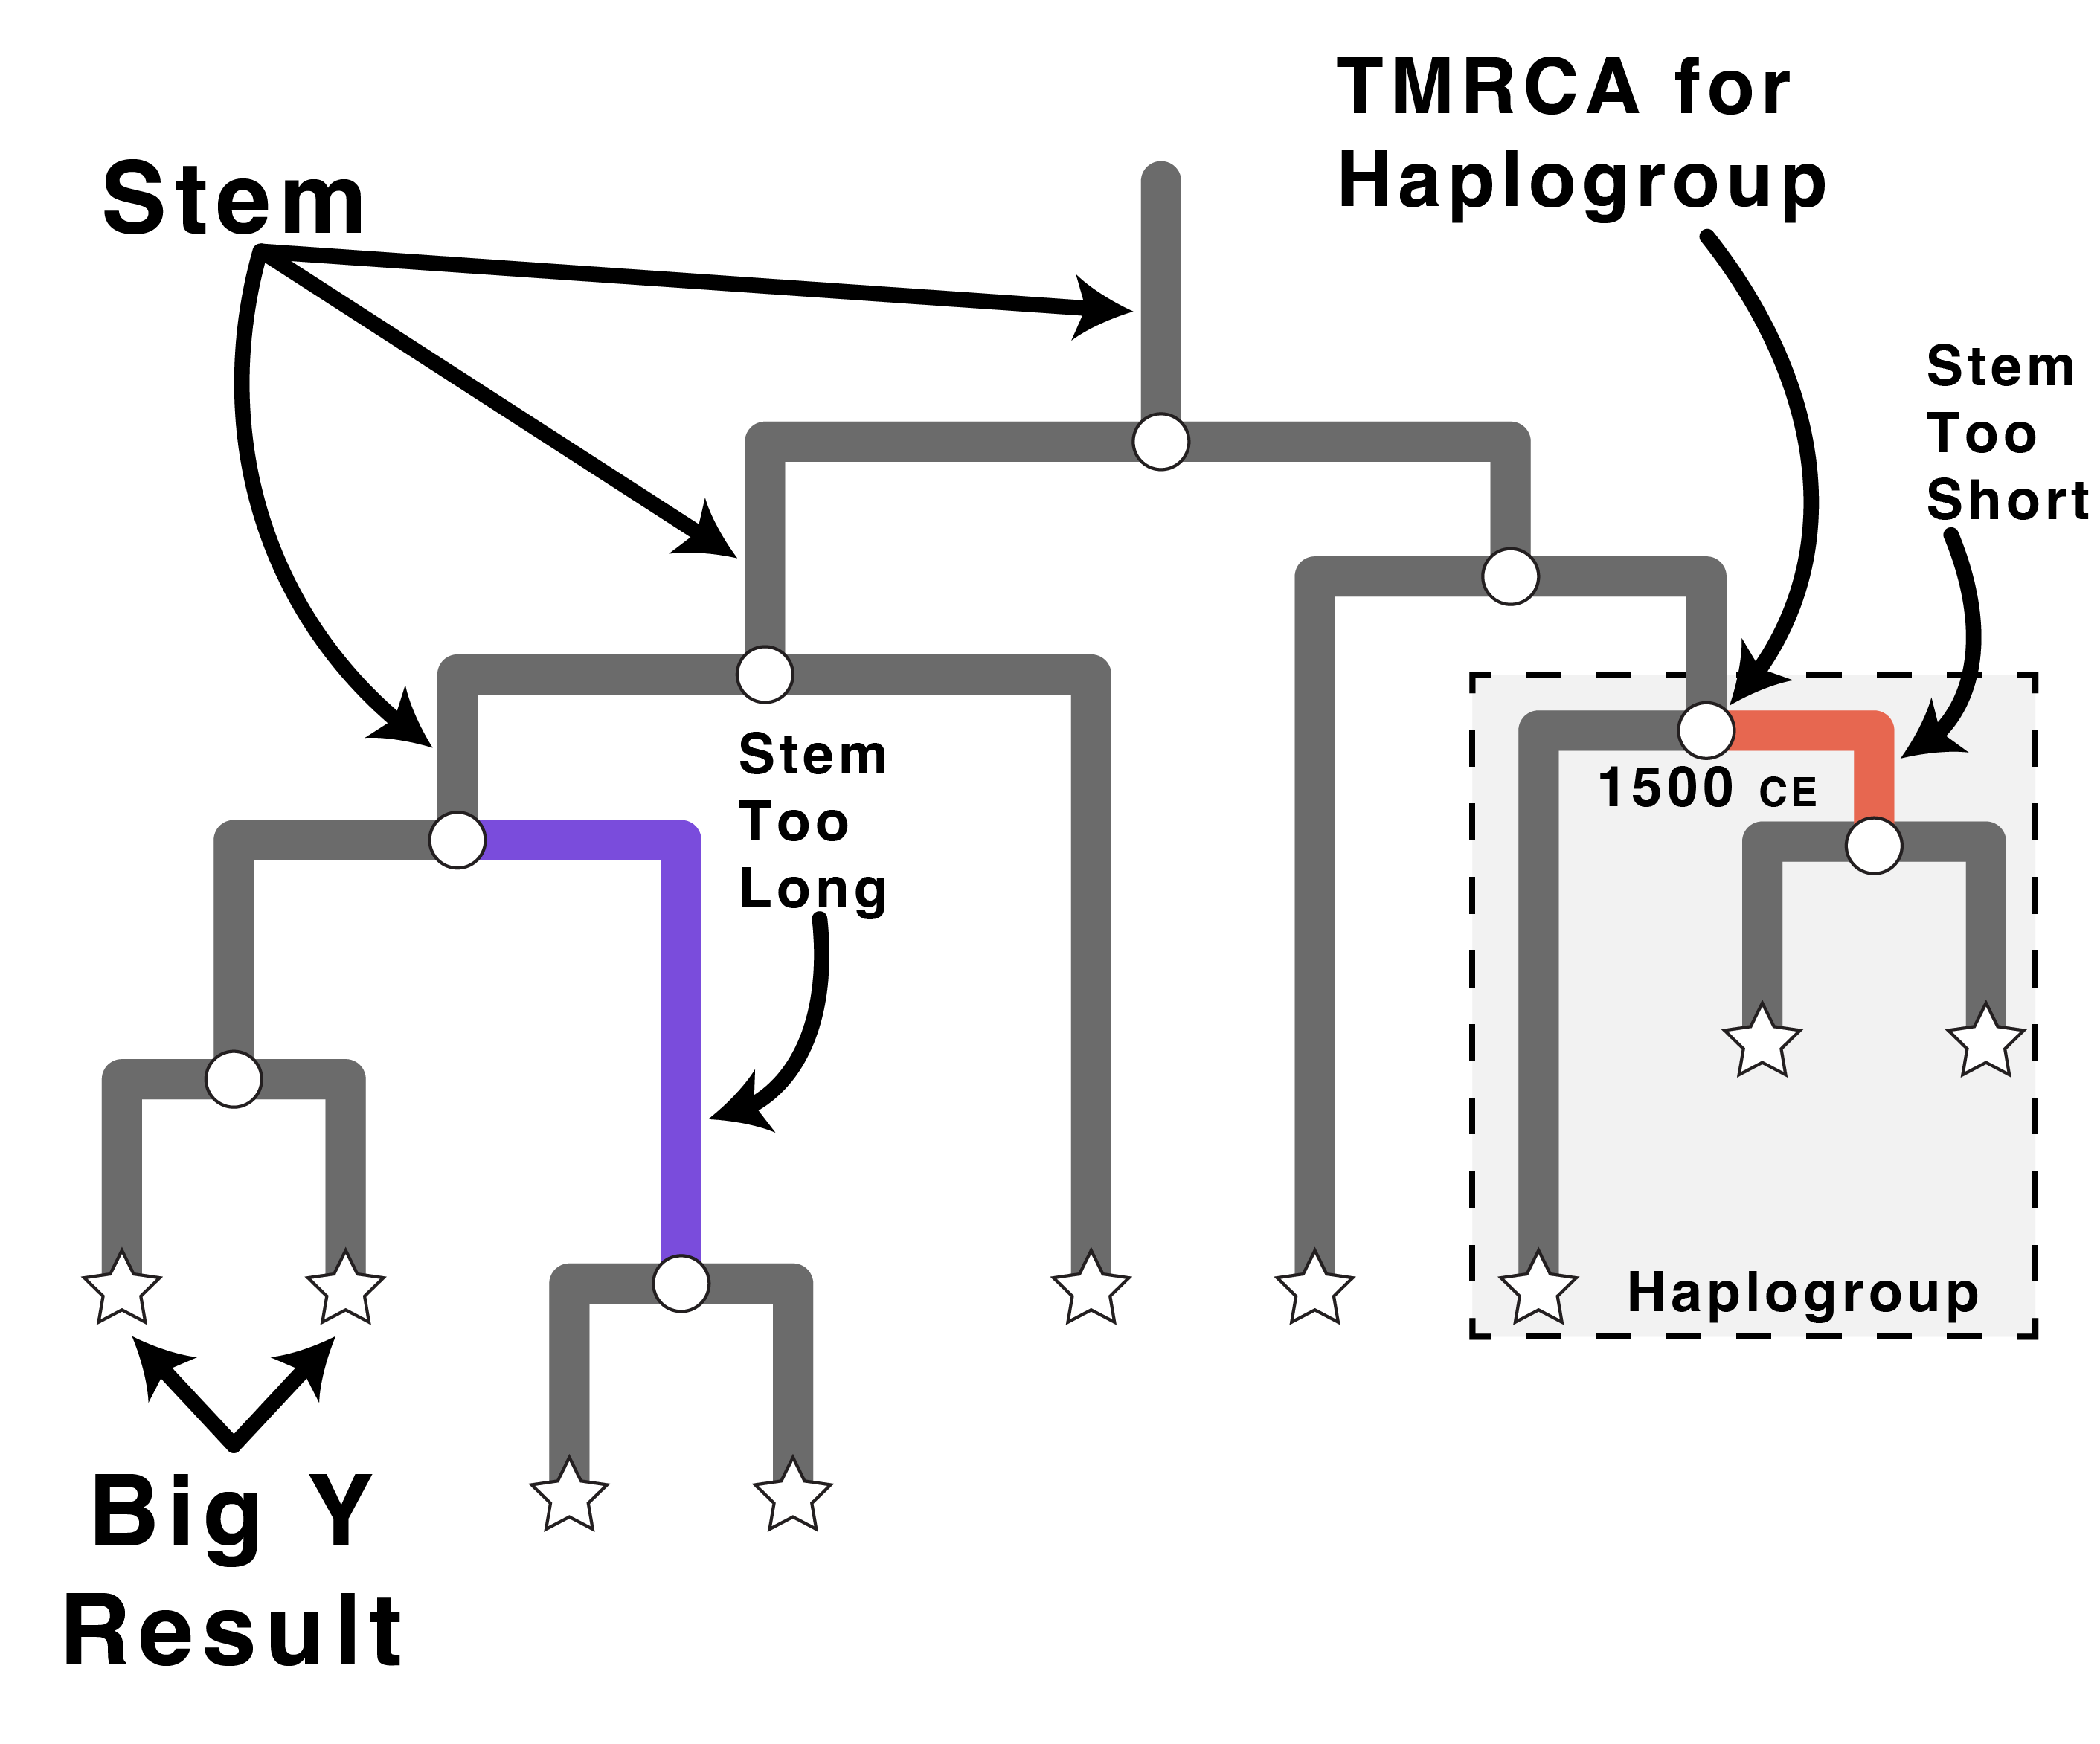
A strict clock assumes mutations accumulate at a perfectly predictable rate. Every tip ends up equidistant from the root, the tree is ultrametric, and the arithmetic is trivial: T = D/2μ. Decades of work show that trees are not like this.
Rates vary, which is called heterotachy. Demographic swings drive part of it: bottlenecks, rapid expansion, shifting generation times. The rest comes from the fact that almost no mutation is exactly neutral. Most are nearly neutral, and large populations purge mildly deleterious variants faster, so growth alone changes how many mutations survive. Others simply hitchhike alongside variants that do affect fitness. Even strictly neutral mutations accumulate faster when population size oscillates or generations overlap.
A relaxed clock gives every stem its own local rate. The hard part is identifying which stems genuinely differ, across a tree with more than 50,000 of them.
Sir John Stewart of Bonkyll
Stewart’s genealogy is documented, so his haplogroup has a known answer to check against. Under the old strict-clock method his lineage R-S781 came out at a mean path length of 1397 CE, adjusted down to 1466 CE to remove paradoxes where a node dated older than its own parent. The final published estimate rounded to 1500 CE. Stewart was born around 1246. The true value fell outside the 95% confidence interval.
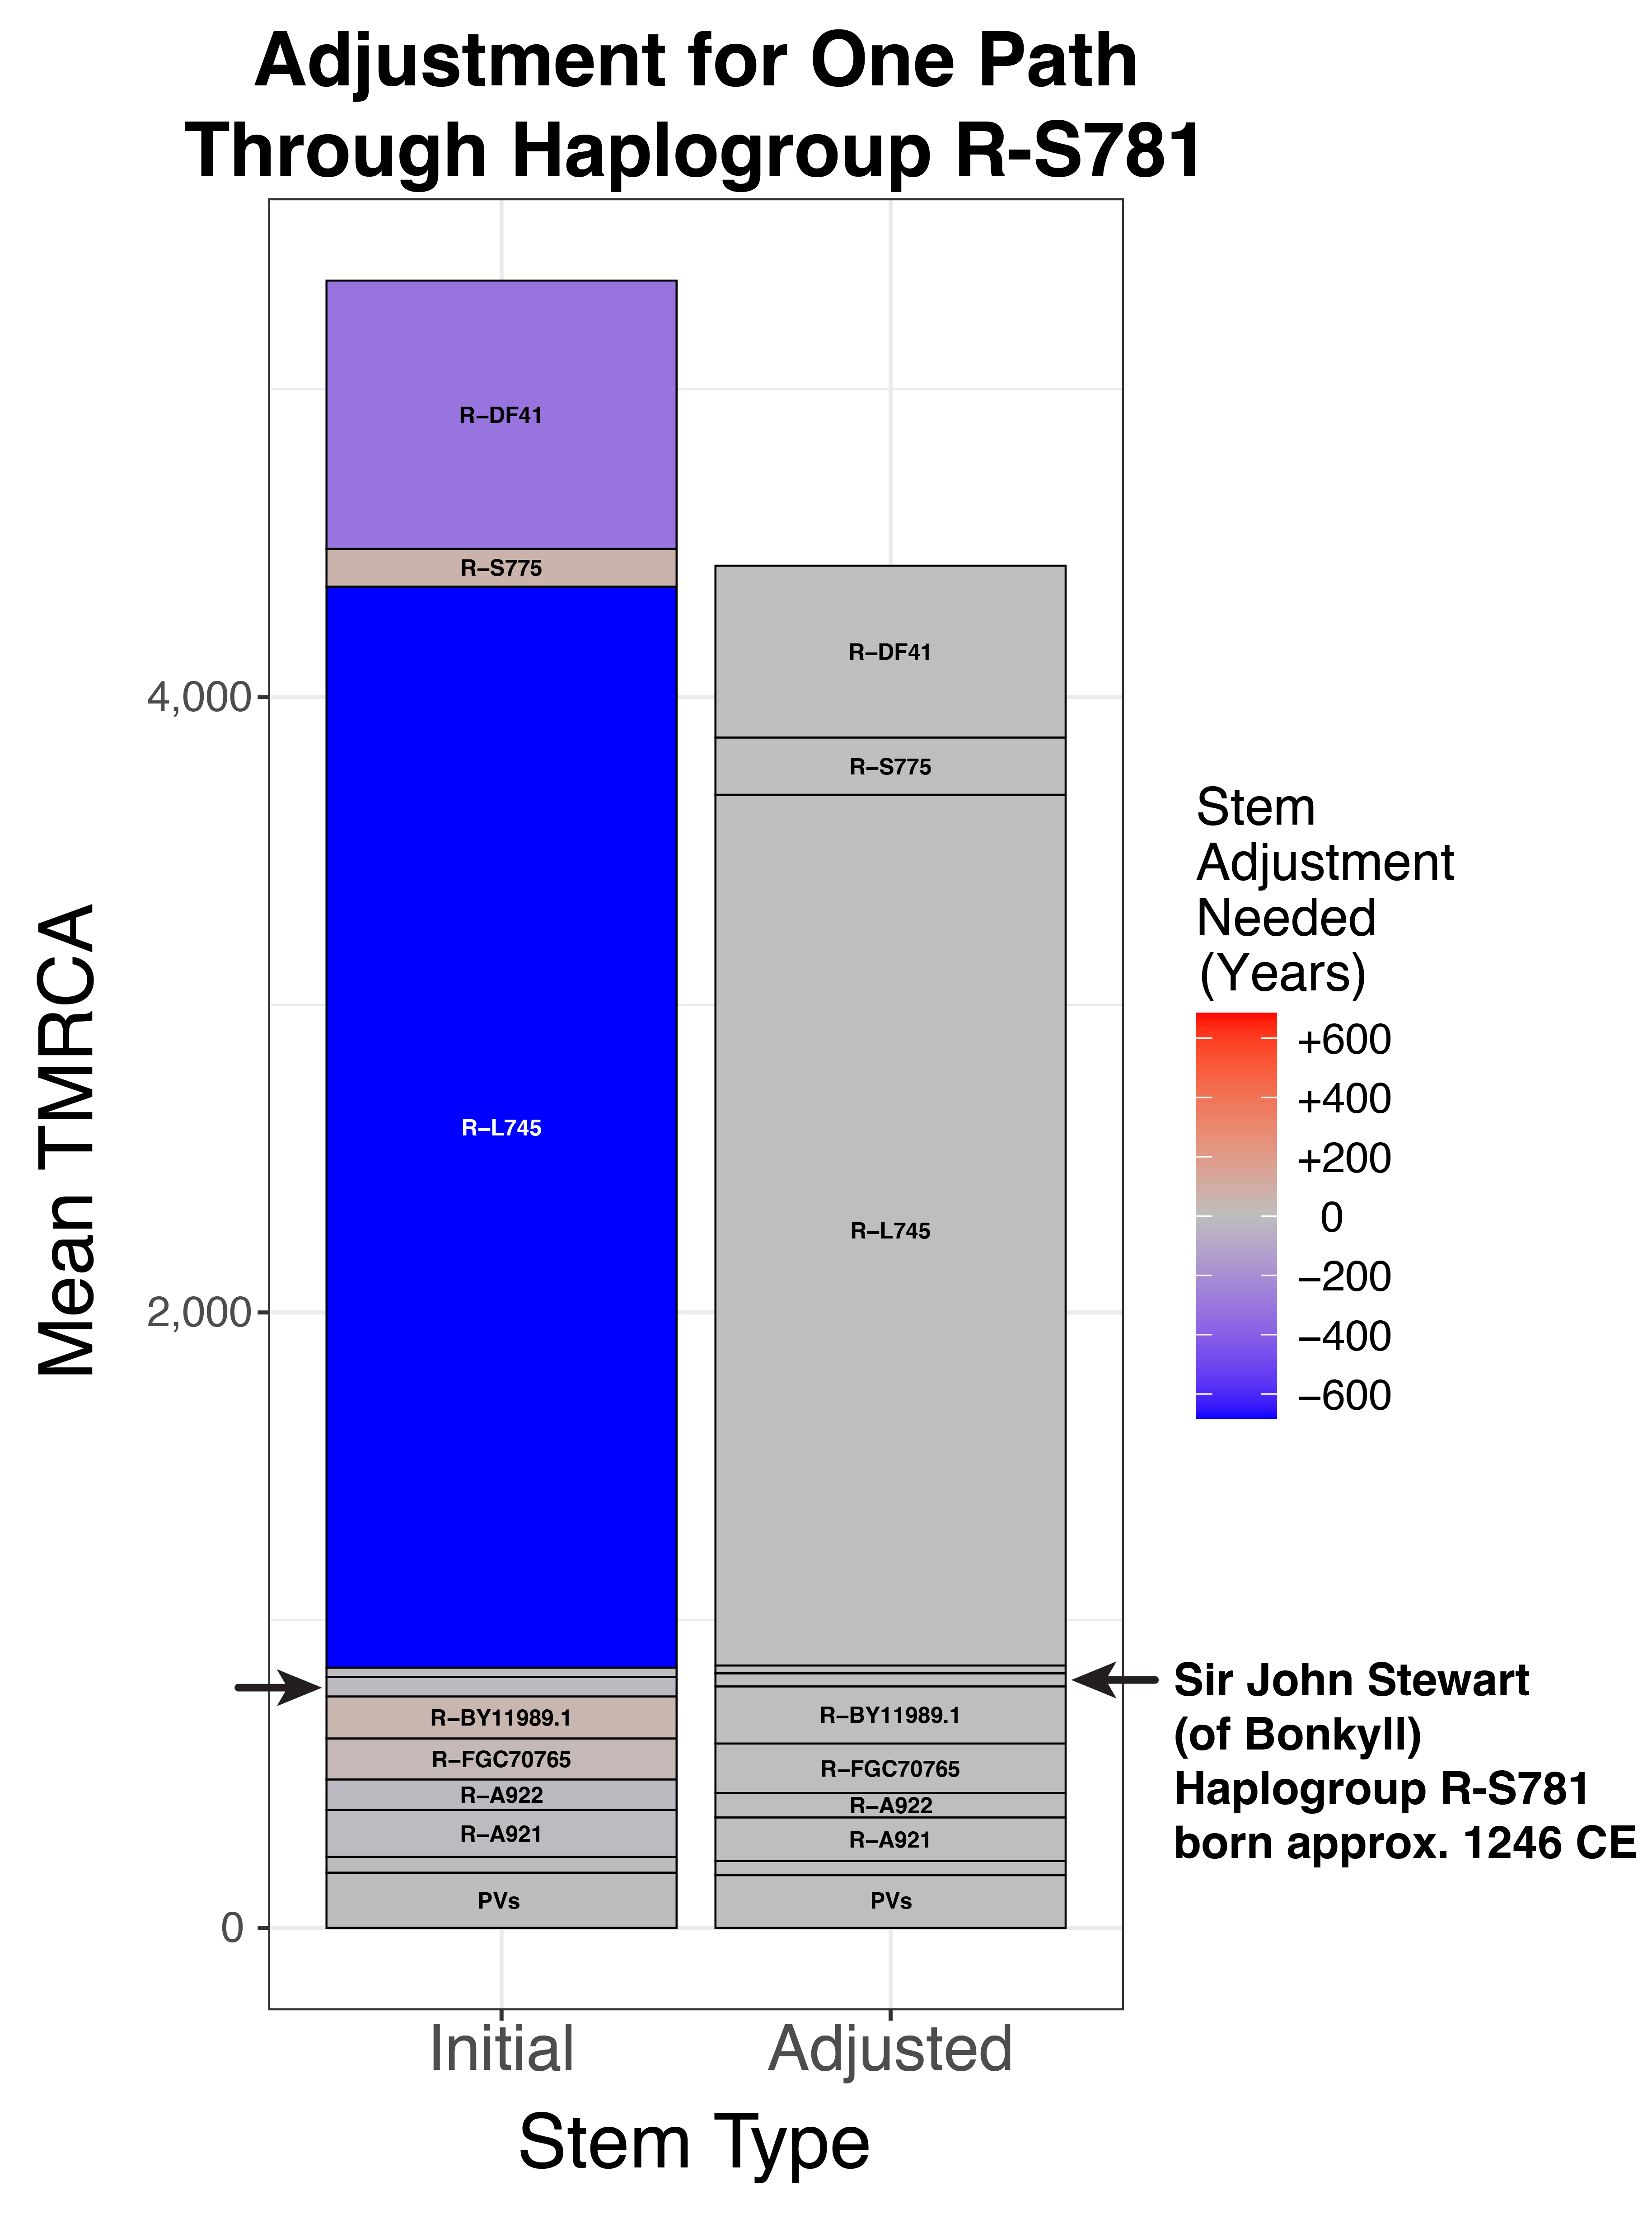
Most of the error traced to one stem. Above Stewart sits R-L745, and under a strict clock of 121 years per SNP the stem above it measured 3,513 years. Weighing all stems across the tree against the validation data put it at 2,830 years, implying roughly 98 years per SNP through that period. Removing those 683 years pushes everything below it older.
The relaxed clock estimate lands at 785 years ago, or 1237 CE, against a documented birth around 1246. The strict clock missed by more than two centuries and excluded the right answer from its interval.
I developed the age estimation method used across the Y tree. It handles variable coverage across the callable region rather than assuming it away, since branch length in years depends on how much of the Y was actually read: T = S / (μ × C), where S is SNP count and C is coverage. For haplogroups younger than about 2,000 years, SNP-based and STR-based stem lengths are estimated separately and combined through a general additive model, because STRs carry useful signal at exactly the timescale where SNPs are sparse. The method drives the public Y-DNA Discover tool and the relationship reports built on it.
Technical details
The published description of this pipeline appears in the supplementary methods of the Beethoven paper, and it is now out of date. That version used a modified PATHd8 to convert mean path length into divergence time, calibrated against an alignment of 91 Big Y sequences spanning the major backbone clades under a BEAST strict clock with a non-parametric Coalescent Bayesian Skyline tree prior. PATHd8 has since been dropped entirely in favour of LSD‘s relaxed clock, which is what runs today and what dates Mitotree.
Calibration uses documented genealogies from customers: birth years on Big Y kits, patrilineal trees with names and dates, and confirmed most recent common ancestors between matches. Those same records serve as the validation set, which is how a case like Stewart’s exposes a systematic bias rather than looking like noise.
Written up for a general audience in two parts on the FamilyTreeDNA blog: the update and the methods, which I wrote.
Tree search as a methods problem in its own right
Searching for a good tree means moving through a space of possible topologies too large to enumerate. Often parts of that topology are already settled, and the search should respect them. That is a constrained search, and it is exactly what Mitotree’s divide-and-conquer stage depends on: build a global constraint tree first, then use it to partition the intensive analyses.
Most phylogenetics programs enforce constraints the obvious way. Generate every rearrangement, then check each one for compliance and discard the violations. Checking costs time, and the time is spent on moves that were never going to be kept.
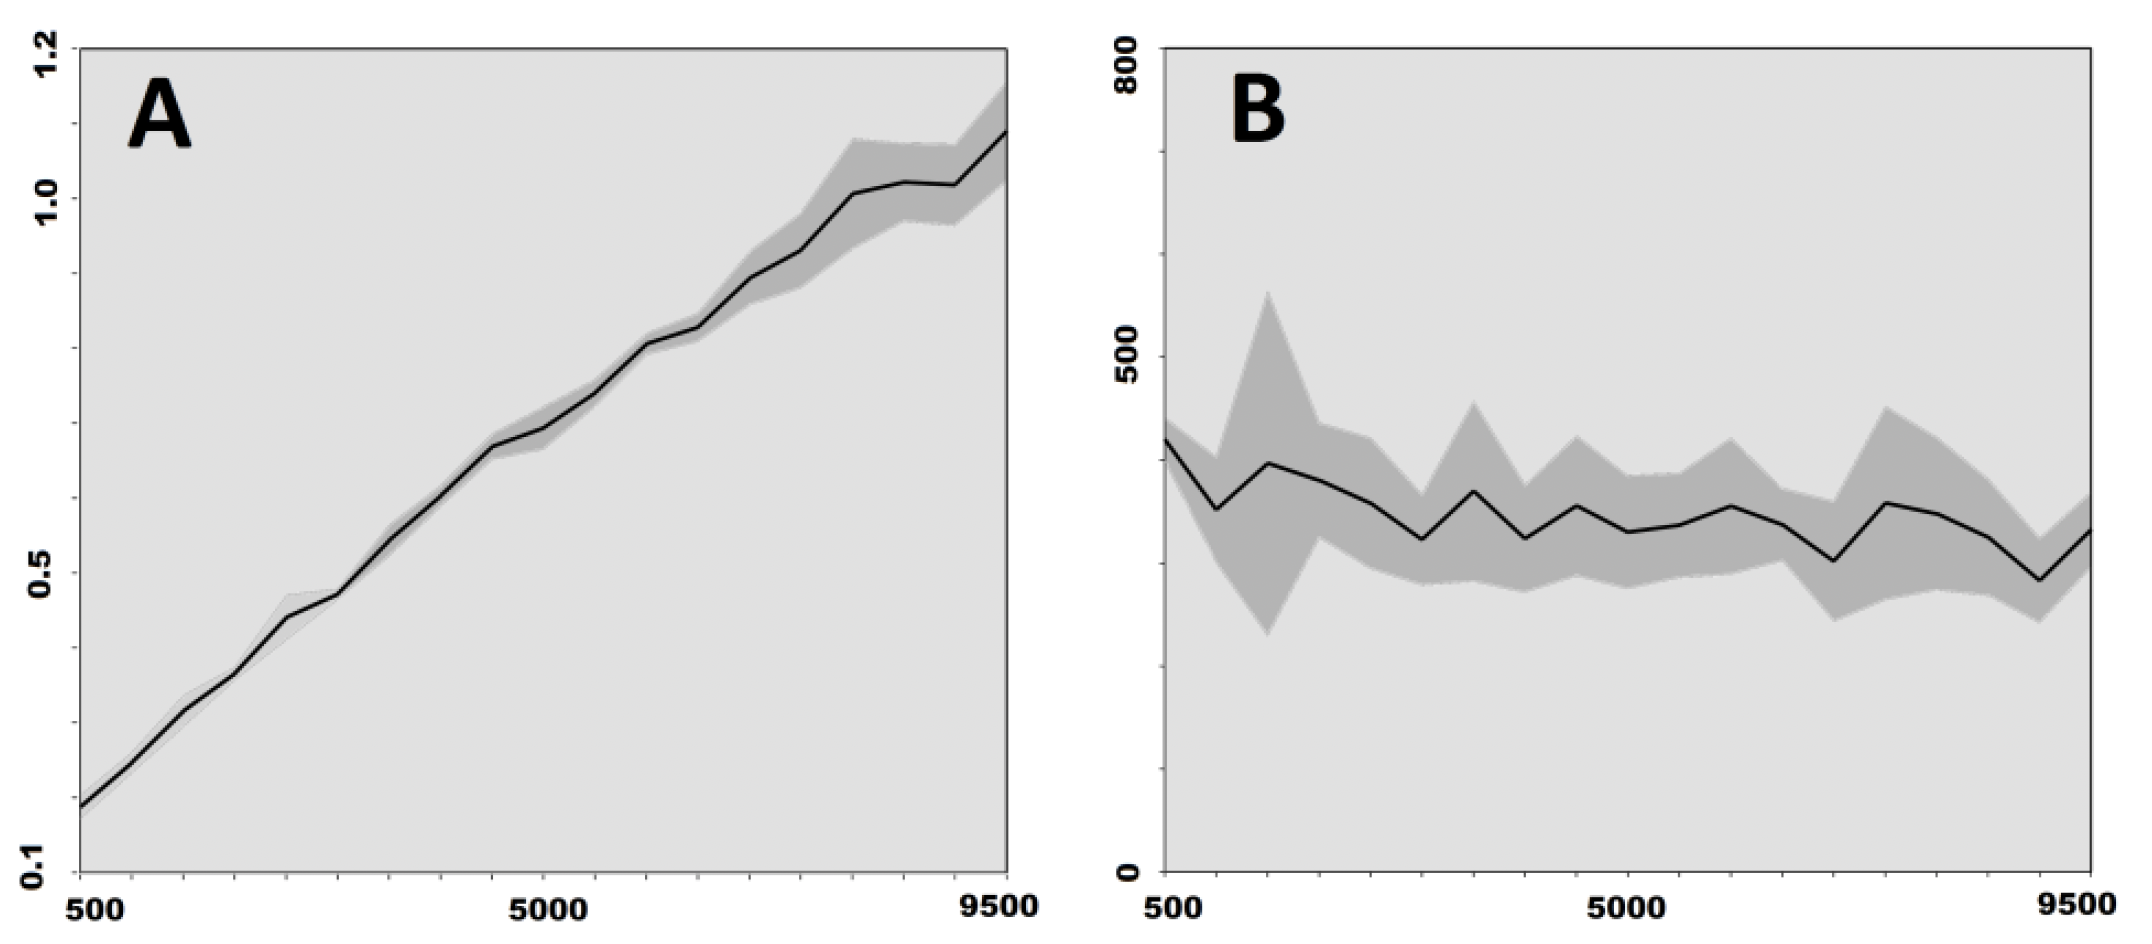
The alternative is to never generate them. Node-blocking pre-partitions the search space so that a move violating a constraint is never proposed, which costs zero evaluation time rather than a small amount of it. In TNT it runs at least 300 times faster than group membership variables, and the gap widens as more groups are constrained. Conventional checking gets slower the more you constrain; node-blocking gets faster.
The method has limits, and the paper is specific about them. Node-blocking applies cleanly to positive constraints where no taxa float, or where the same taxa float for every constrained group. Positive constraints with different floating taxa, or negative constraints, still need bitwise group representation, which is memory-hungry and yields far smaller gains. Greedy Wagner tree building can also fail to satisfy positive and negative constraints simultaneously, and the paper works through approaches to make that failure much less likely.
Pablo Goloboff wrote TNT, the software the Mitotree searches run on, so this came out of needing the method rather than looking for a topic. The application in the paper is the 175,000-haplotype Mitotree dataset.
Papers from this work
- Maier P.A., Runfeldt G., Estes R.J., Goloboff P.A., Detsikas J., Burke A.J., Sager M.T., Vilar M.G. Mitotree: the universal human mitochondrial reference phylogeny at 10× the resolution. Cladistics, in review. DOI
- Goloboff P.A., Maier P.A. Phylogenetic tree searches under topological constraints. Cladistics, in review.
- Maier P.A., Runfeldt G., Estes R.J., Vilar M.G. (2022). African mitochondrial haplogroup L7: a 100,000-year-old maternal human lineage discovered through reassessment and new sequencing. Scientific Reports 12(1), 10747. DOI · PDF